But after digging through Google, YouTube, Vimeo, DailyMotion, C-SPAN, and the Twitter archives myself, it seemed to be true: an iconic moment of ’90s political pop culture appeared to be completely missing from the internet.
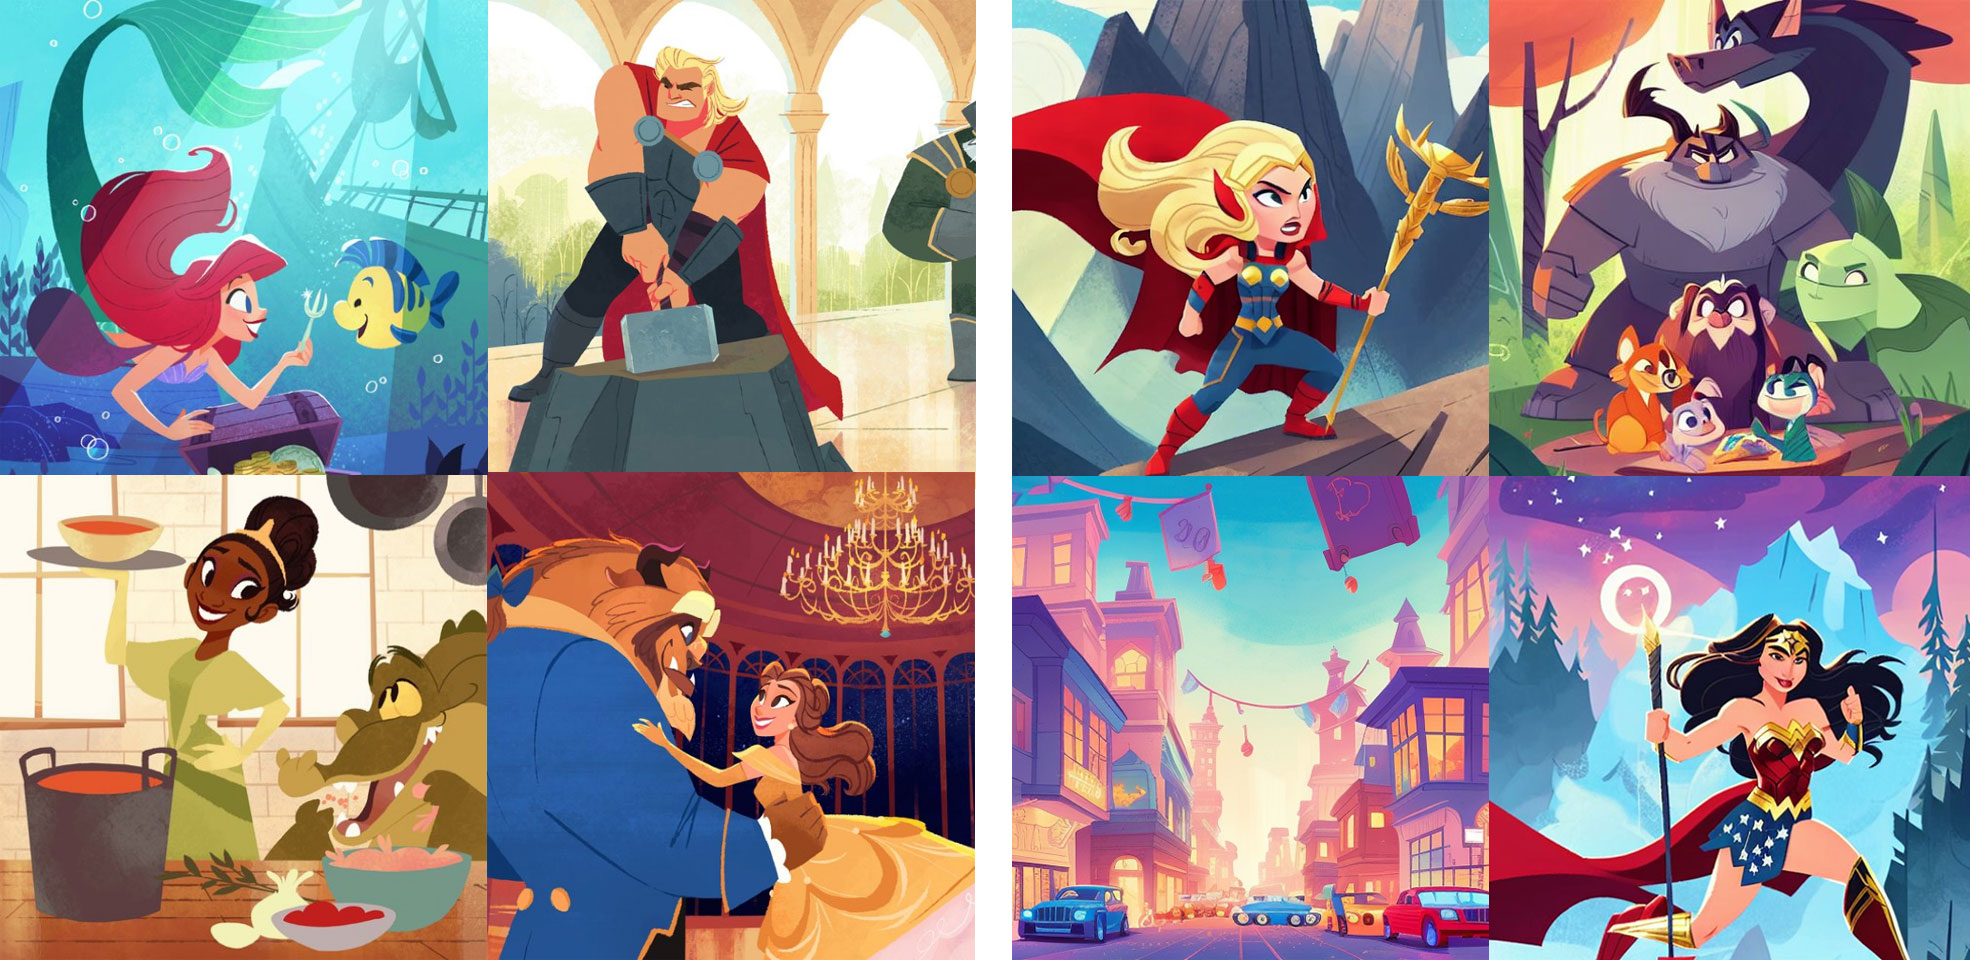
Last weekend, Hollie Mengert woke up to an email pointing her to a Reddit thread, the first of several messages from friends and fans, informing the Los Angeles-based illustrator and character designer that she was now an AI model.
The day before, a Redditor named MysteryInc152 posted on the Stable Diffusion subreddit, “2D illustration Styles are scarce on Stable Diffusion, so I created a DreamBooth model inspired by Hollie Mengert’s work.”
Using 32 of her illustrations, MysteryInc152 fine-tuned Stable Diffusion to recreate Hollie Mengert’s style. He then released the checkpoint under an open license for anyone to use. The model uses her name as the identifier for prompts: “illustration of a princess in the forest, holliemengert artstyle,” for example.
Artwork by Hollie Mengert (left) vs. images generated with Stable Diffusion DreamBooth in her style (right)
After we cancelled XOXO in the early days of the pandemic, I spent much of 2020 wondering if there was any way to recreate the unique experience of a real-world festival like XOXO online: the serendipity of meeting new people while running between venues, getting drawn into conversations with strangers and old friends, stepping in and out of conversations as simply as walking away.
Those explorations ended up in Skittish, a colorful and customizable browser-based 3D world that let you talk to others nearby with your voice while controlling a goofy animal character. It was weird and silly and I loved it.
Sadly, for a number of reasons, I’ve decided to shut it down this December.
There isn’t enough demand to keep it going, probably a combination of an overall decline in demand for virtual events and its niche featureset, and it requires ongoing support and maintenance that’s hard for me to provide on my own.
Yesterday, Meta’s AI Research Team announced Make-A-Video, a “state-of-the-art AI system that generates videos from text.”
We’re pleased to introduce Make-A-Video, our latest in #GenerativeAI research! With just a few words, this state-of-the-art AI system generates high-quality videos from text prompts.
Like he did for the Stable Diffusion data, Simon Willison created a Datasette browser to explore WebVid-10M, one of the two datasets used to train the video generation model, and quickly learned that all 10.7 million video clips were scraped from Shutterstock, watermarks and all.
In addition to the Shutterstock clips, Meta also used 10 million video clips from this 100M video dataset from Microsoft Research Asia. It’s not mentioned on their GitHub, but if you dig into the paper, you learn that every clip came from over 3 million YouTube videos.
So, in addition to a massive chunk of Shutterstock’s video collection, Meta is also using millions of YouTube videos collected by Microsoft to make its text-to-video AI.
Here’s a little mystery for you: there are multiple reports of a mysterious voice grunting, moaning, and groaning on American Airlines’ in-flight announcement systems, sometimes lasting the duration of the flight — and nobody knows who’s responsible or how they did it.
Actor/producer Emerson Collins was the first to post video, from his Denver flight on September 6:
The weirdest flight ever. These sounds started over the intercom before takeoff and continued throughout the flight. They couldn’t stop it, and after landing still had no idea what it was. pic.twitter.com/F8lJlZHJ63