As AI-generated art platforms like DALL-E 2, Midjourney, and Stable Diffusion explode in popularity, online communities devoted to sharing human-generated art are forced to make a decision: should AI art be allowed?
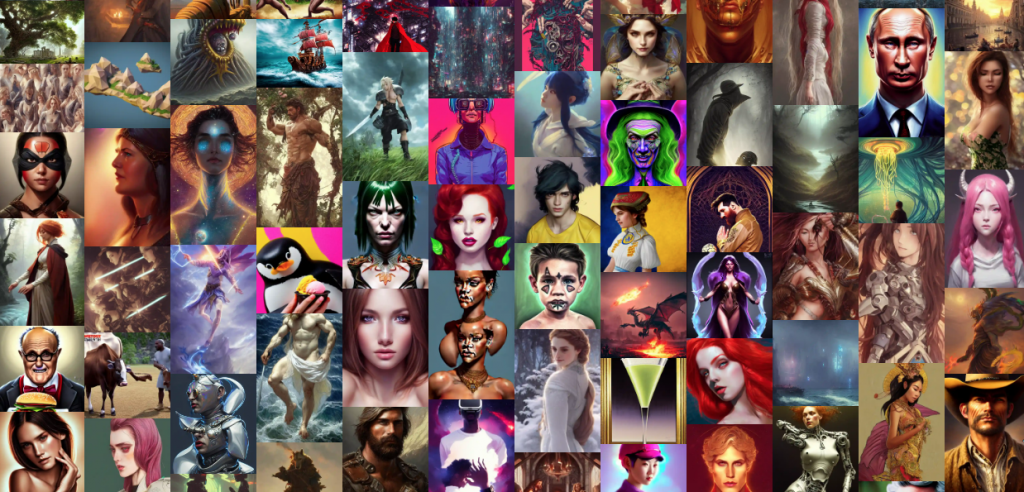
Collage of dozens of images made with Stable Diffusion, indexed by Lexica
On Sunday, popular furry art community Fur Affinity announced that AI-generated art was not allowed because it “lacked artistic merit.” (In July, one AI furry porn generator was uploading one image every 40 seconds before it was banned.) Their new guidelines are very clear:
Content created by artificial intelligence is not allowed on Fur Affinity.
AI and machine learning applications (DALL-E, Craiyon) sample other artists’ work to create content. That content generated can reference hundreds, even thousands of pieces of work from other artists to create derivative images.
Our goal is to support artists and their content. We don’t believe it’s in our community’s best interests to allow AI generated content on the site.
There’s no shortage of amazing games so far this year, but my personal favorite is an underdog: Perfect Tides, a ’90s-esque point-and-click adventure about growing up as a teen on a sleepy island resort town in the early 2000s, finding an escape from real-life feelings of loneliness and loss in discussion forums and late-night AIM chats.
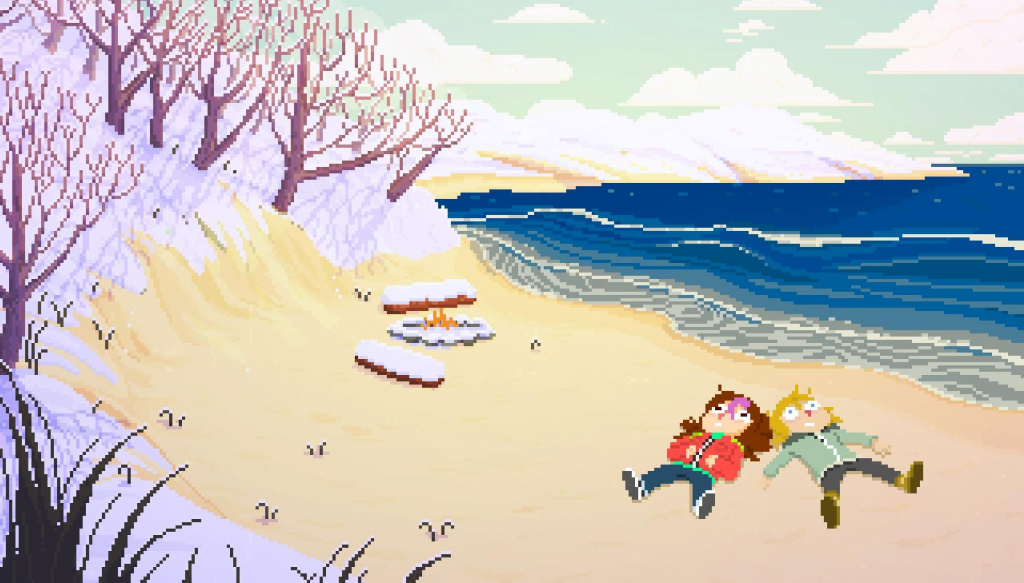
Mara and her friend Lily on the beach… definitely not on drugs
The first game from Meredith Gran, creator of the decade-long comic series Octopus Pie, it approaches challenging subjects with the confidence of someone who created narrative comics every week for ten years. I can’t think of another comics artist who has dived into game design like this, but it pays off with uniquely charming pixel art and animation, colorful writing, and a story that genuinely moved me by the end. It navigates complex feelings about family, old friends, and new loves, while also being genuinely funny.
One of the biggest frustrations of text-to-image generation AI models is that they feel like a black box. We know they were trained on images pulled from the web, but which ones? As an artist or photographer, an obvious question is whether your work was used to train the AI model, but this is surprisingly hard to answer.
Sometimes, the data isn’t available at all: OpenAI has said it’s trained DALL-E 2 on hundreds of millions of captioned images, but hasn’t released the proprietary data. By contrast, the team behind Stable Diffusion have been very transparent about how their model is trained. Since it was released publicly last week, Stable Diffusion has exploded in popularity, in large part because of its free and permissive licensing, already incorporated into the new Midjourney beta, NightCafe, and Stability AI’s own DreamStudio app, as well as for use on your own computer.
But Stable Diffusion’s training datasets are impossible for most people to download, let alone search, with metadata for millions (or billions!) of images stored in obscure file formats in large multipart archives.
So, with the help of my friend Simon Willison, we grabbed the data for over 12 million images used to train Stable Diffusion, and used his Datasette project to make a data browser for you to explore and search it yourself. Note that this is only a small subset of the total training data: about 2% of the 600 million images used to train the most recent three checkpoints, and only 0.5% of the 2.3 billion images that it was first trained on.
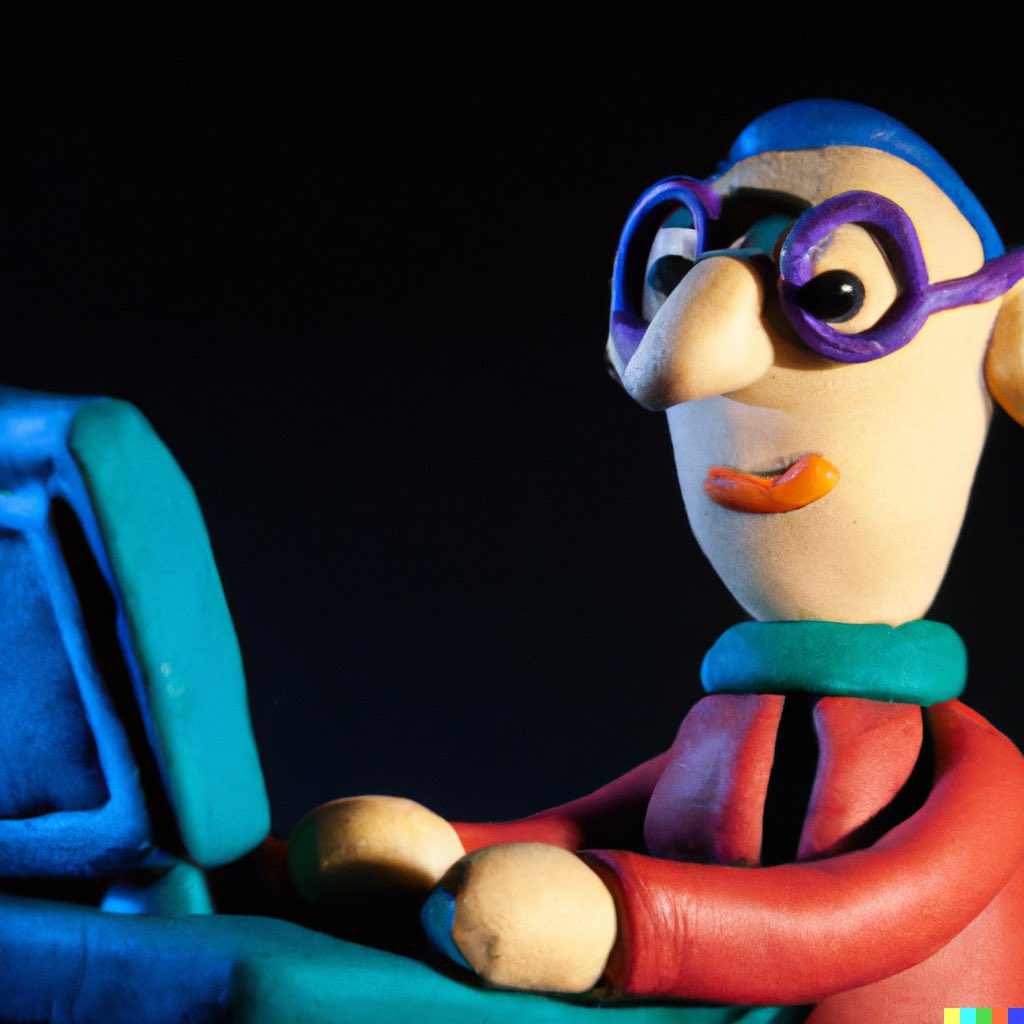
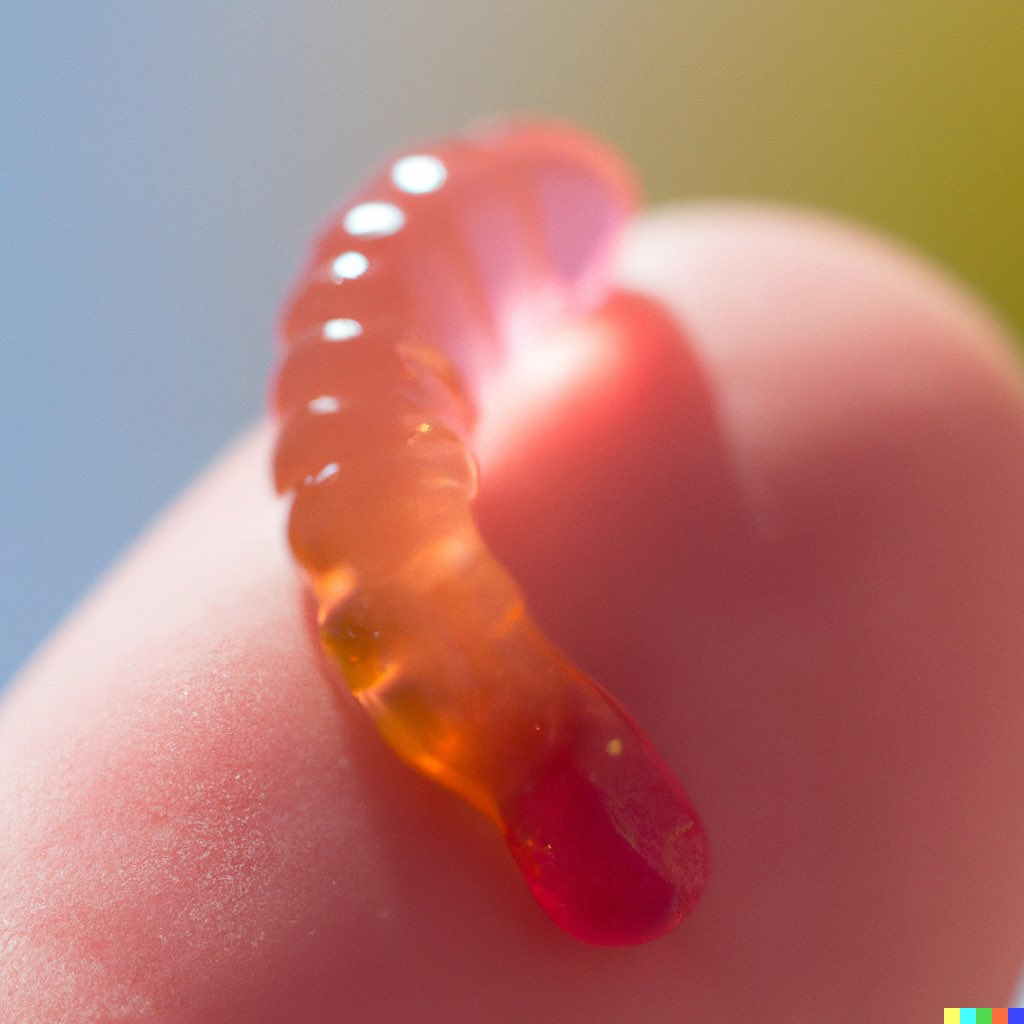
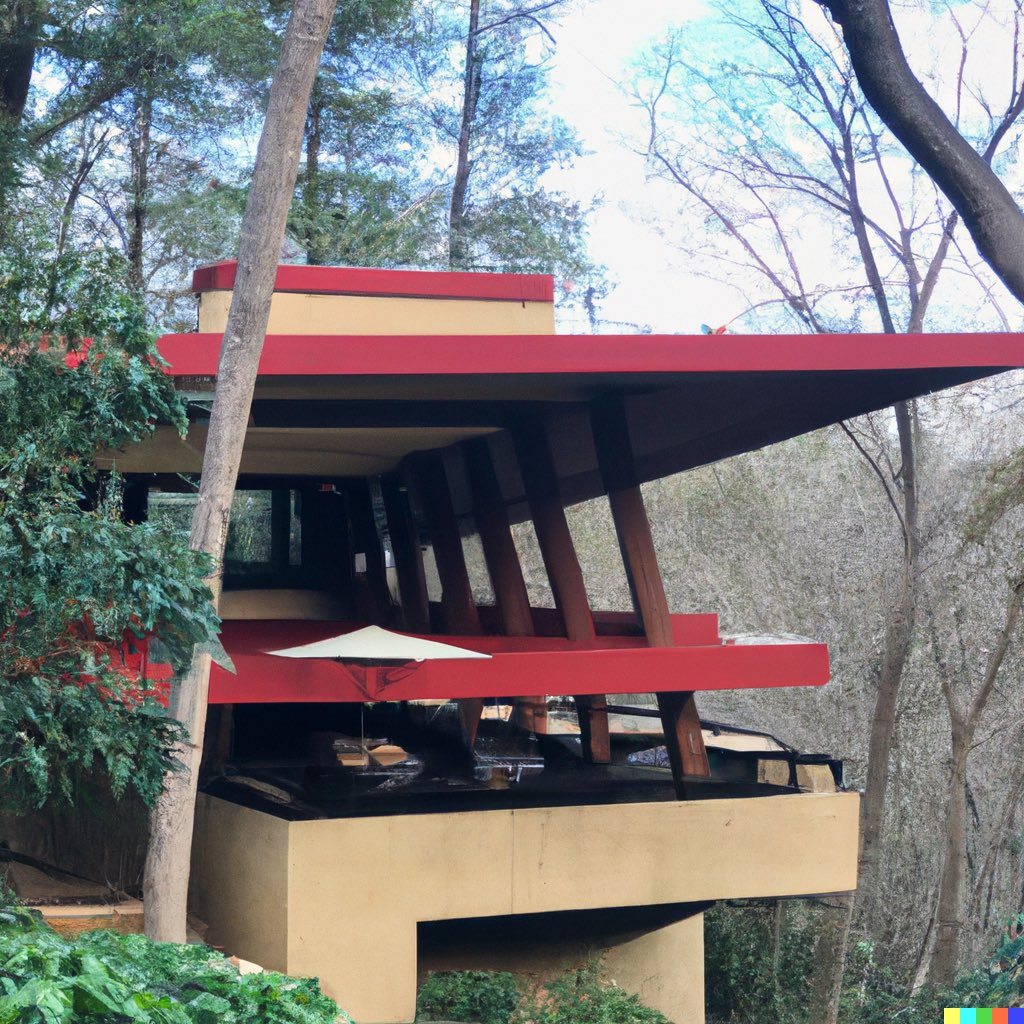
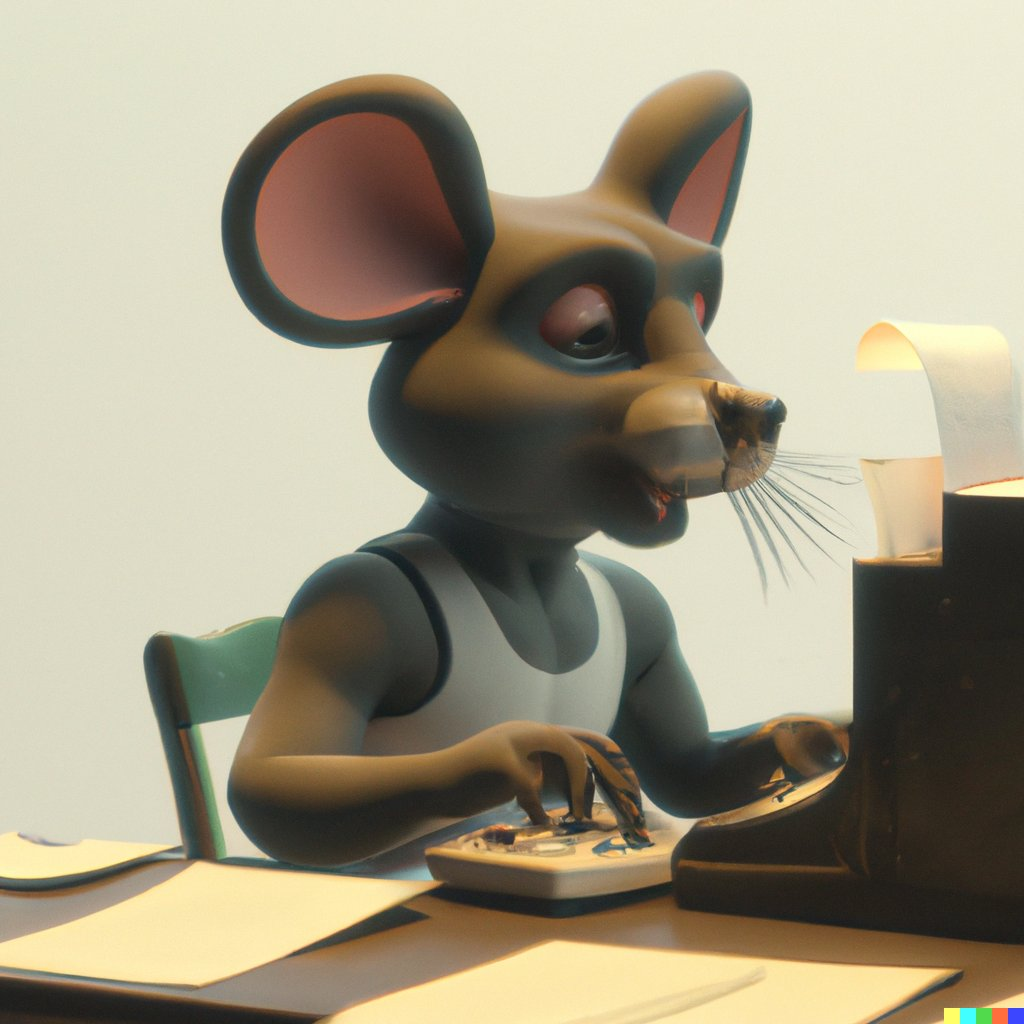
“plasticine nerd working on a 1980s computer”“macro photo of beautiful living gummy candy worm on a human hand”“Combination Pizza Hut and Frank Lloyd Wright’s Fallingwater”
DALL·E 2 diligently hallucinated each image out of noise from the compressed latent space, multi-dimensional patterns discovered in hundreds of millions of captioned images scraped from the internet.
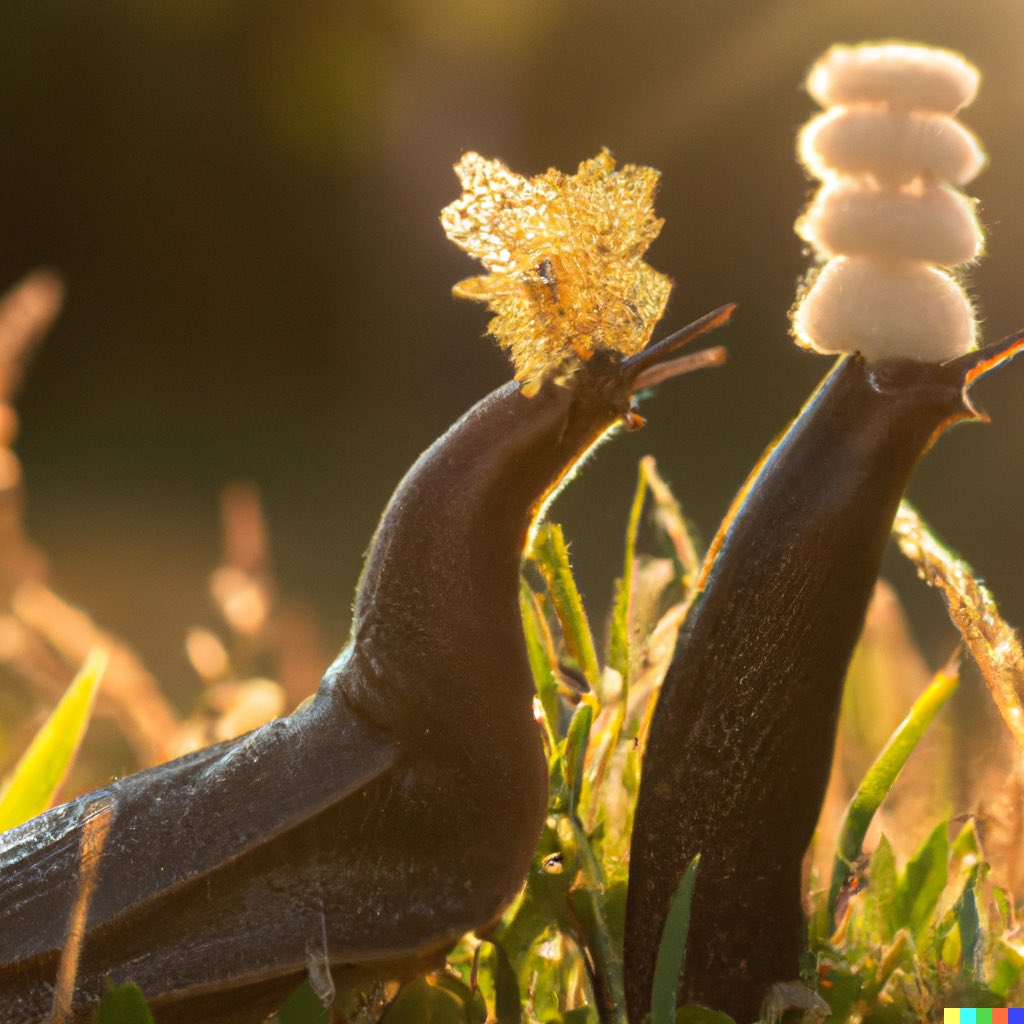
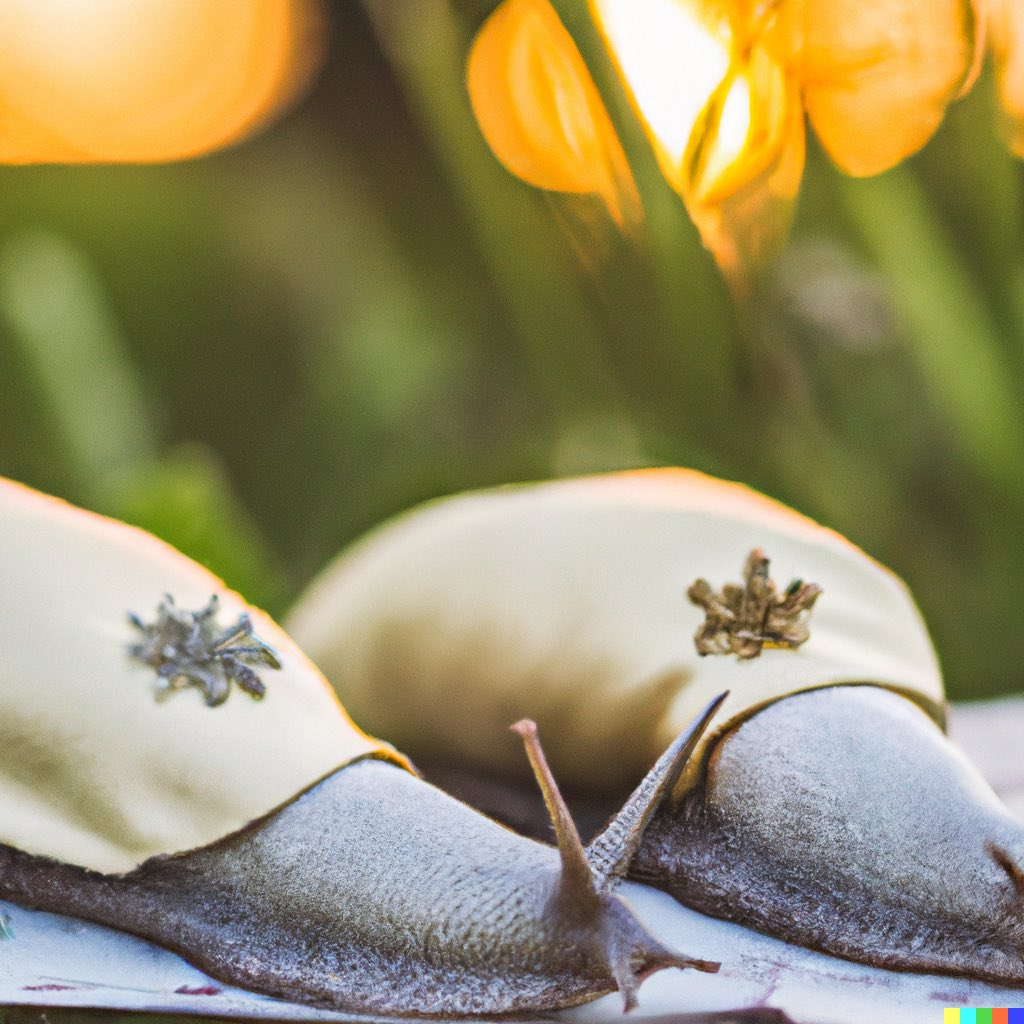
“two slugs in wedding attire getting married, stunning editorial photo for bridal magazine shot at golden hour”
The prompt that finally melted my brain was the one above, with images of slugs getting married at golden hour. I originally specified a “tuxedo and wedding dress” with predictable results, but changing it to “wedding attire” gave the AI the flexibility to depict variations of what slugs might marry in, like headdresses made of cotton balls and honeycomb.
I’ve never felt so conflicted using an emerging technology as DALL·E 2, which feels like borderline magic in what it’s capable of conjuring, but raises so many ethical questions, it’s hard to keep track of them all.
There are the many known issues that OpenAI’s acknowledged and worked to mitigate, like racial or gender biases in its image training set, or the lengths they’ve gone to avoid generating sexual/violent content or recognizable celebrities and trademarked characters.
But it opens profound questions about the ethics of laundering human creativity:
Is it ethical to train an AI on a huge corpus of copyrighted creative work, without permission or attribution?
Is it ethical to allow people to generate new work in the styles of the photographers, illustrators, and designers without compensating them?
Is it ethical to charge money for that service, built on the work of others?
There are basic fundamental questions about whether it’s even legal: these are largely untested waters in copyright law and it seems destined to end up in court. Training deep learning models on copyrighted material may be fair use, but only a judge can decide that. (The fact that OpenAI’s removing some results from the image training set, like celebrity faces and Disney/Marvel characters, suggests they’re well aware of angering the biggest litigants.)
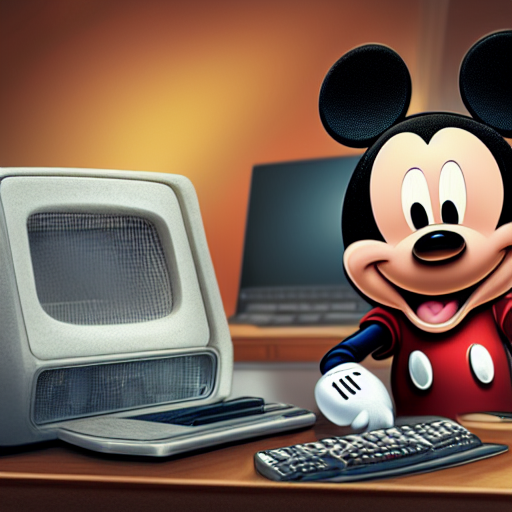
“realistic 3d rendering of mickey mouse working on a vintage computer doing his taxes” on DALL·E 2 (left) vs. Stable Diffusion (right)
As these models improve, it seems likely to reduce demand in some paid creative services, from stock photography to commissioned illustrations. I empathize with the concerns of artists whose work was silently used to train commercial products in their style, without their consent and with no way to opt-out.
The world was just starting to grapple with the implications of this technology when, on Monday, a company called Stability AI released its Stable Diffusion text-to-image AI publicly.
Stable Diffusion is free, open-source, runs on your own computer, and ships without any of the guardrails and content filters of its predecessors. It comes with a Safety Classifier enabled by default that tries to determine if a generated image is NSFW, but it’s easily disabled.
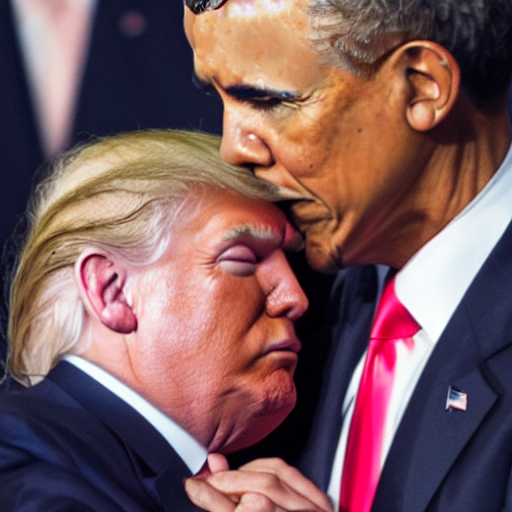
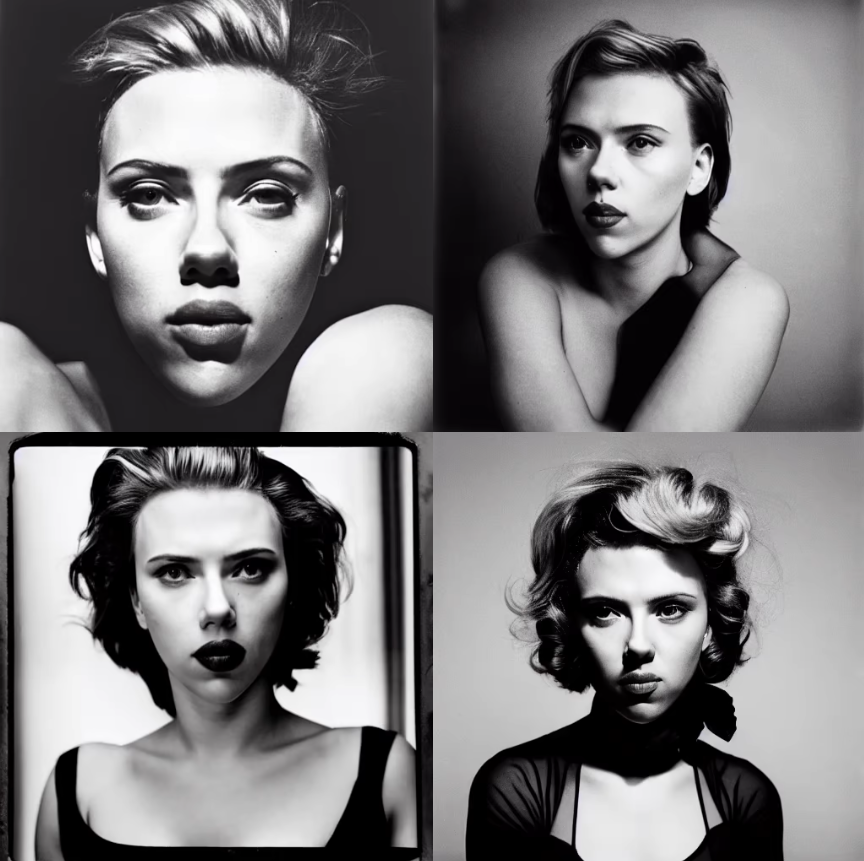
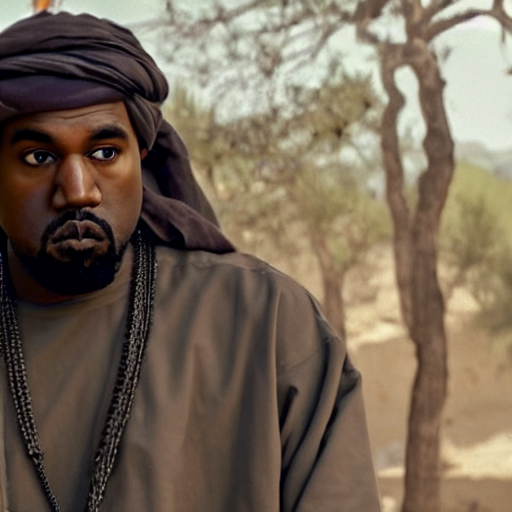
“Obama comforting Trump”“photo of Scarlett Johansson by Diane Arbus” “Kanye West in the Taliban”Samples of celebrity images generated by Stable Diffusion users
Unlike existing AI platforms like DALL·E 2 and Midjourney, Stable Diffusion can generate recognizable celebrities, nudity, trademarked characters, or any combination of those. (Try searching Lexica, the newly-launched Stable Diffusion search engine, for example output.)
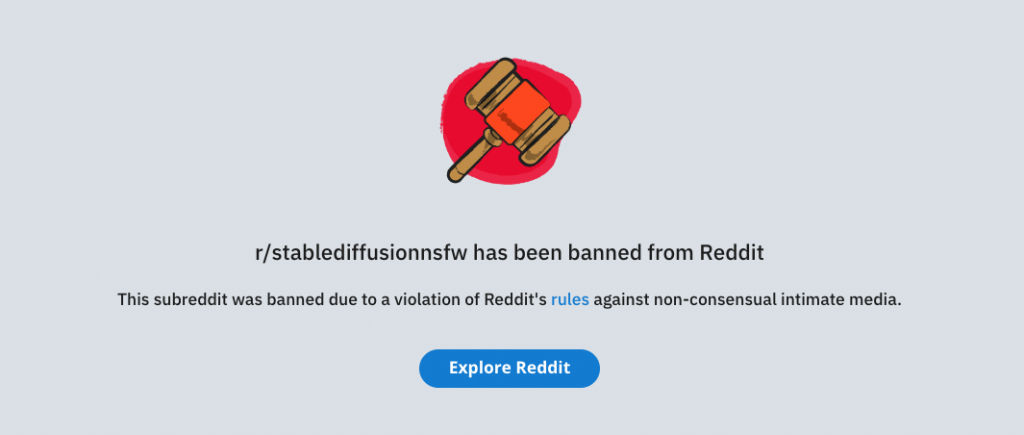
Releasing an uncensored dream machine into the wild had some predictable results. Two days after its release, Reddit banned three subreddits devoted to NSFW imagery made with Stable Diffusion, presumably because of the rapid influx of AI-generated fake nudes of Emma Watson, Selena Gomez, and many others.
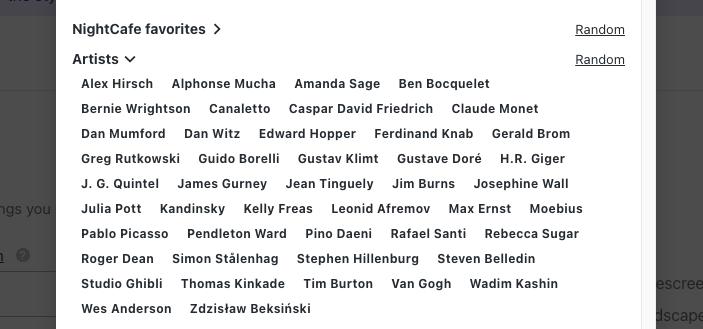
The permissive license on Stable Diffusion allows commercial services to implement its AI model, such as NightCafe, which encourages paying customers to generate art in the styles of living artists like Pendleton Ward, Greg Rutkowski, Amanda Sage, Rebecca Sugar, and Simon Stålenhag, who has spoken out against the practice.
List of artist modifiers in NightCafe
On top of it, Stable Diffusion’s terms state that every image generated with their Dream Studio is effectively public domain, under the CC0 1.0 Public Domain license. They make no claim over the copyright of images generated with the self-hosted Stable Diffusion model. (OpenAI’s terms says that images created with DALL·E 2 are their property, with customers granted a license to use them commercially.)
A common argument I’ve seen is that training AI models is like an artist learning to paint and finding inspiration by looking at other artwork, which feels completely absurd to me. AI models are memorizing the features found in hundreds of millions of images, and producing images on demand at a scale unimaginable for any human—thousands every minute.
The results can be surprising and funny and beautiful, but only because of the vast trove of human creativity it was trained on. Stable Diffusion was trained on LAION-Aesthetic, a 120-million image subset of a 5 billion image crawl of image-text pairs from the web, winnowed down to the most aesthetically attractive images. (OpenAI has been more cagey about its sources.)
There’s no question it takes incredible engineering skill to develop systems to analyze that corpus and generate new images from it, but if any of these systems required permission from artists to use their images, they likely wouldn’t exist.
Stability AI founder Emad Mostaque believes the good of new technology will outweigh the harm. “Humanity is horrible and they use technology in horrible ways, and good ways as well,” Mostaque said in an interview two weeks ago. “I think the benefits far outweigh any negativity and the reality is that people need to get used to these models, because they’re coming one way or another.” He thinks that OpenAI’s attempts to minimize bias and mitigate harm are “paternalistic,” and a sign of distrust of their userbase.
Today we all made the World a more creative, happier and communicative place.
More to come in the next few days but I for one can’t wait to see what you all create.
In that interview, Mostaque says that Stability AI and LAION were largely self-funded from his career as a hedge fund manager, and with additional resources, they’ve created a 4,000 A100 cluster with the support of Amazon that “ranks above JUWELS Booster as potentially the tenth fastest supercomputer.”
On Monday, Mostaque wrote that they plan to use those compute resources to expand to other AI-generated media: audio next month, and then 3D and video. I’d expect Stability AI to approach these new models in the same way, with little concern over their potential for misuse by bad actors, and with even less attention spent addressing the concerns of the artists and creators whose work makes them possible.
Like I said, I’m conflicted. I love playing with new technology, and I’m excited about the creative potential of these new tools. I want to feel good about the tools I use.
I don’t trust OpenAI for a bunch of reasons, but at least they seemed to try to do the right thing with their various efforts to reduce bias and potential harm, even if it’s sometimes clumsy.
Stable Diffusion’s approach feels irresponsible by comparison, another example of techno-utopianism unmoored from the reality of the internet’s last 20 years: how an unwavering commitment to ideals of free speech and anti-censorship can be deployed as a convenient excuse not to prevent abuse.
For now, generative AI platforms are some of the most resource-intensive projects in the world, leading to a vanishingly small number of participants with access to vast compute resources. It would be nice if those few companies would act responsibly by, at the very least, providing an opt-out for those who don’t want their work in future training data, finding new ways to help artists that do choose to participate, and following the lead of OpenAI in trying to minimize the potential for harm.
I don’t pretend to know where these things will go: the risks may be overblown and we may be at the start of a massive democratization in the creation of art, or these platforms may make the already-precarious lives of artists harder, while opening up new avenues for deepfakes, misinformation, and online harassment and exploitation. I’d really like to see more of the former, but it won’t happen on its own.
Hard to believe, but I started blogging 20 years ago today with this short post.
In my first ten years of writing, I published 415 posts and over 13,000 links. And in the last ten years, I published 136 posts and a little over 5,000 links, a pretty big drop from the ten years before.
There are some pretty obvious reasons why my posting slowed since 2012:
XOXO started that year, which became a big creative outlet for me, as well as a big time sink.
My long-form writing shifted elsewhere, with my column in WIRED and as a member of The Message publication on Medium, while short-form writing continued to land on Twitter.
I became more focused on quality than quantity, with a higher bar for what made it here.
I was less motivated to invest time in writing, in part because fewer people were reading.
I still enjoy writing though, and have no intention of stopping any time soon.
Ten years ago, I wrote a roundup of my favorite posts from my first decade of blogging, and I thought I’d do the same thing for 2012-2021. If you missed them the first time around, I hope you check them out this time. Looking back on the last ten years, I’m proud of so many of these pieces.
2012
Introducing Playfic. Announcing the launch of Playfic, a tool for writing and sharing Inform 7 interactive fiction games in the browser. Nearly 3,000 games have been published so far, I rounded up some highlights in 2013. (These days, I’d recommend using Borogove.)
The Perpetual, Invisible Window Into Your Gmail Inbox. I wrote about Unroll.me and similar apps that were quietly requesting access to all your email, an issue that exploded five years later when it was revealed they were selling user info to Uber, among others.
A Patent Lie: How Yahoo Weaponized My Work. This article blew up pretty big, in which I talk about how tech corporations encourage developers to patent their work, ostensibly for defensive purposes, only to find them used in litigation to stop innovation, popularizing the term “weaponized patents” in the process.
Instagram’s Buyout: How Does It Measure Up? Crunching the numbers on Instagram’s billion-dollar sale to Facebook against other notable acquisitions to see how it measured up. Instagram made $26 billion in ad revenue last year, more than Facebook itself, so a pretty smart deal.
Introducing XOXO. Launched on Kickstarter, sold every ticket in 50 hours.
The Unified Theory of XOXO. Once the dust settled from the first XOXO, I wrote about what we were trying to do and the decisions we made — all of which are still part of the festival today.
The New Prohibition. Occasionally, my posts end up turning into conference talks, like in this Creative Mornings presentation.
The Death of Upcoming.org. I found out Yahoo was shutting down Upcoming like everyone else, with 11 days’ notice. With Archive Team’s help, we were able to collectively archive the vast majority of the site, allowing me to later restore nearly every event to its original URL.
‘JIF’ Is the Format. ‘GIF’ Is the Culture. Steve Wilhite may have designed the GIF format, but the looping animated GIF was a product of the web, invented eight years later.
72 Hours of #Gamergate. Analyzing over 316,000 tweets that mentioned #Gamergate to spot trends and visualize the network, including clear evidence that most supporters were using newly-created accounts.
Diary of a Corporate Sellout. A personal post about the risks that come from selling your startup when it’s also an online community. “When you sell the house, you’re not just selling a house. You’re selling everyone inside.”
Playing With My Son. One of my all-time favorites, the story of playing videogame history with my son in (roughly) chronological order. I repurposed this one for a talk at Gel 2015, with my son in the front row.
2015
Pirating the 2015 Oscars: HD Edition. An interesting shift in screener leaks: pirates didn’t want them anymore because DVDs were increasingly considered poor-quality. “Pirates are now watching films at higher quality than the industry insiders voting on them.”
Never Trust A Corporation To Do A Library’s Job. My love letter to the Internet Archive, and Google’s failure to live up to their original mission statement to organize the world’s information.
Remembering XOXO 2016. 2016 was a busy year, between opening and closing the XOXO Outpost (our massive workspace for indie artists), working on the Upcoming reboot, and holding the fifth year of the festival. I didn’t get a lot of writing done.
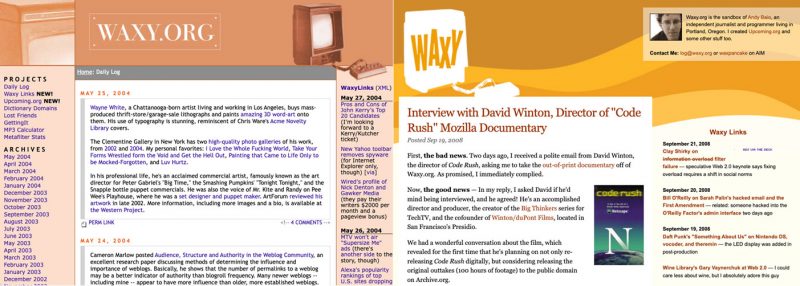
Redesigning Waxy. I did squeeze in a redesign though, and some thoughts on blogging in 2016.
Pogo’s Politics. This post about Australian remix artist Pogo still gets traffic any time his name comes up, and people become aware of his repulsive views on women. “It’s hard to truly enjoy art made by someone you can’t respect.”
You Think You Know Me. Announcing my wife Ami’s first card game, which I help edit and design, now published under the moniker Pink Tiger Games. Her fourth game, Lost for Words, is coming out later this year, this one co-designed with our son, Eliot. It’s turned into a real family business!
2018
A Tribute to YouTube Annotations. Six weeks before YouTube retired its annotations feature, I collected as many notable examples as I could find. Sadly, they’re all no longer interactive.
Demi Adejuyigbe at XOXO 2018. My only post about XOXO 2018, which was more than double the size in a new venue and absolutely exhausting, but still really memorable. Lizzo played the closing party and then sang karaoke with everyone! I regret not writing more about it while it was fresh in my mind.
Why You Should Never, Ever Use Quora. The most regressive archiving policy of any online community, it’s likely to be an epic loss of collected knowledge when they eventually close down.
2019
Dad. I don’t talk about my personal life often, but I sometimes make an exception for close friends and family I’ve lost.
The House on Blue Lick Road. 2020’s best game was a 3D real estate listing of a sprawling hoarder house. I had to know more, so I picked up the phone and called the owner.
Colin’s Bear Animation, Revisited. Digging into the genealogy of a TikTok meme that bizarrely recreated the dance from Colin’s Bear Animation video, but with no other reference to the original.